 Neurotime
Methodology
How the analysis works
Collection, relevance, sentiment, categorization and grouping turn raw keyword matches into information a team can act on. Each step is described here, with its limitations. Examples are illustrative.
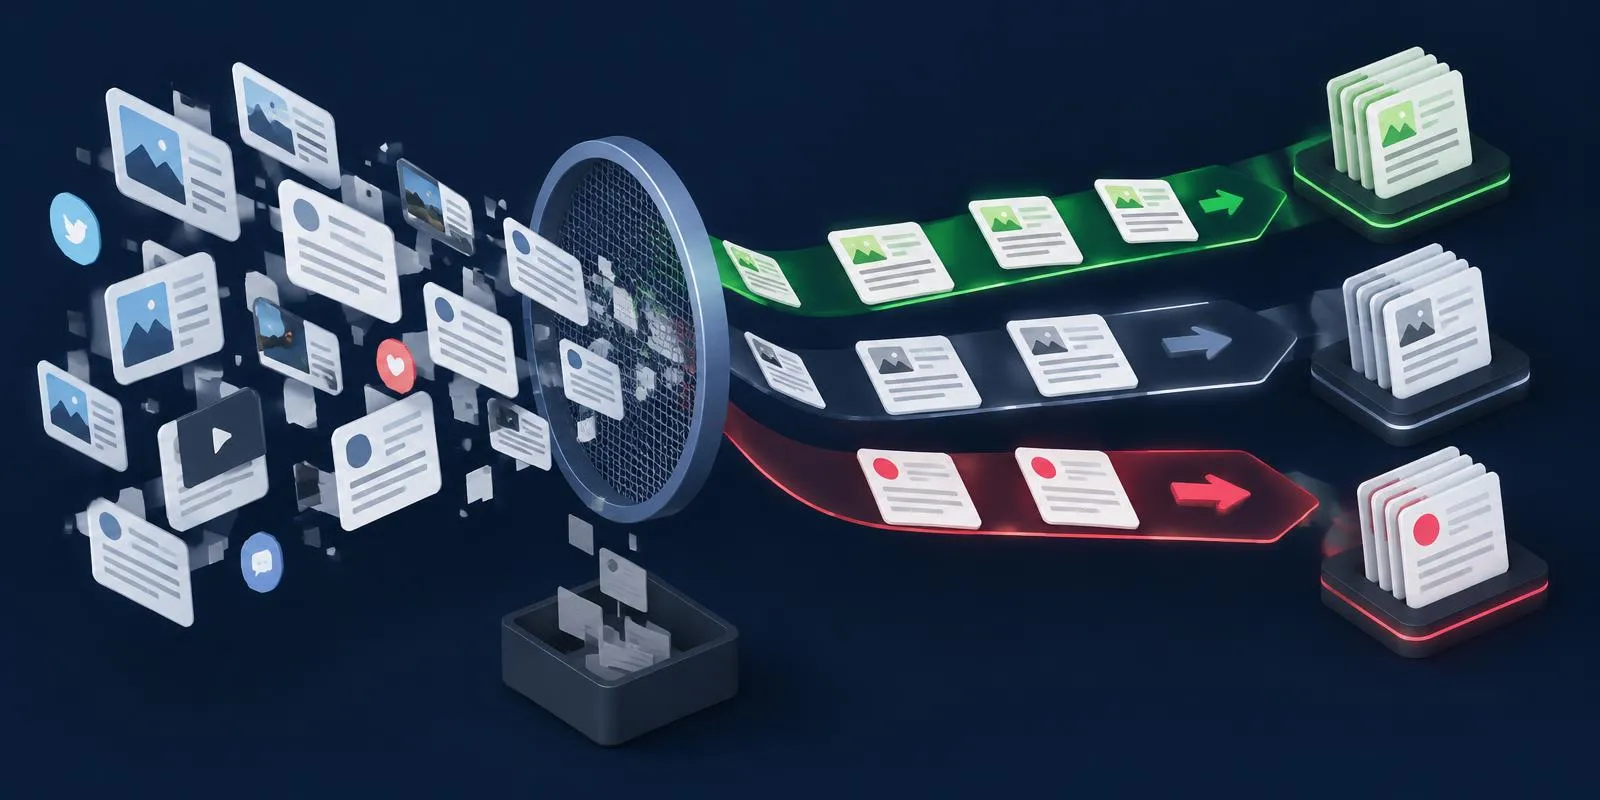
The pipeline at a glance
Every article, post and broadcast passes through the same steps, within minutes of being collected.
0
Collect
Keywords are searched in titles, descriptions and full text; OCR reads text inside images and video frames; TV and radio are recorded 24/7.
1
Relevance
Is this really about the tracked subject? Unrelated matches are removed.
2
Sentiment
Positive, neutral or negative tone toward the subject.
3
Categorization
Which business topic the mention is about.
4
Grouping
Reposts and stories about the same event are grouped together.
1.Relevance
A keyword match is not a mention. Many Azerbaijani brand names are also common words, place names or surnames. Neurotime's relevance models evaluate whether the text is actually about the tracked subject.
Illustrative example: tracking a company called “Ulduz” (star) would match astronomy news, a football club and several people named Ulduz. Relevance filtering keeps only text about the company.
Limitation: very short posts and new names with little context are harder to judge. Tracking rules (variants, exclusions) are tuned with each customer.
2.Sentiment
Each relevant mention is classified as positive, neutral or negative using machine-learning models that analyse the text.
Azerbaijani text brings specific challenges: inflected word forms, mixed Azerbaijani–Russian–English vocabulary, Latin and Cyrillic spellings, sarcasm and quoted criticism inside neutral reporting.
Sentiment refers to the text's tone toward the subject, not to its business impact.
3.Categorization
Mentions are analysed by topic, so a team can see, for example, how much coverage concerns products, service quality, leadership or sponsorships. MediaEye detects, labels and categorizes both text and visual content, using OCR for text inside images and videos.
Categories follow your business questions and can be tailored to your organization.
4.Grouping
Grouping covers several different things that should not be confused: exact duplicates (the same text twice), reposts (one article republished by several sites), similar stories (different articles about the same event) and topic clusters.
MediaEye uses text-similarity analysis to group reposts and related stories, so you see how far one story spread without counting it as dozens of independent articles.
5.Tuning for each customer
Every organization has its own names, products and sensitivities. During onboarding we agree keyword variants (with and without ə, ğ, ş; Latin and Cyrillic; abbreviations), exclusion words and the category list that matches your business questions.
When your team corrects a sentiment or category, or marks a mention as irrelevant, that feedback is used to refine the rules for your project, so results get sharper over the first weeks.
Frequently asked questions
Yes. Relevance, sentiment and lemmatization models are built for Azerbaijani, including inflected forms, mixed Azerbaijani–Russian–English text and Latin or Cyrillic spellings.
Yes. Your team can correct any label in the platform; corrections are reflected in dashboards and reports and help refine your project's rules.
No. Categories are agreed with each customer — for a bank they might be cards, mobile app, branches, loans and sponsorships.
Yes. OCR reads text inside images and video frames, such as a logo on a banner or a headline in a screenshot.
A repost is the same article republished by another site; a similar story is a different article about the same event. Both are grouped, but shown so you can tell them apart.